AI Computing

Move AI from an idea to a working system.

Right-sized desktops, professional GPU workstations and GPU servers for development, fine-tuning, inference, computer vision, simulation and data science — engineered around the model, dataset and software stack.

✓Made in India OEM✓NVIDIA / AMD GPU options✓POC to production pathway✓SLA-led deployment support
Use cases & recommended devices

AI compute sized for what you actually run

GPU memory, CPU, system memory, storage throughput, thermals, power and networking are selected together to avoid expensive bottlenecks.

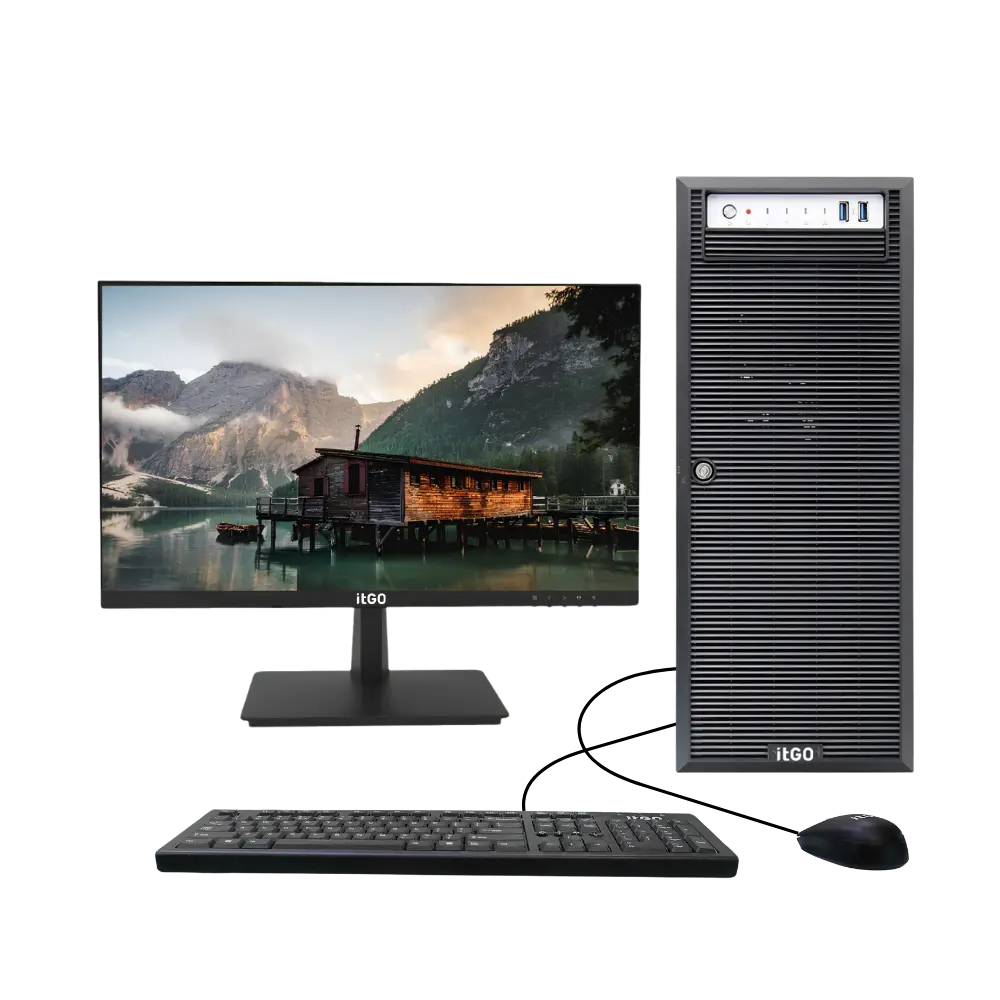
01Learning, Prototyping & Classical MLPython development, data preparation, notebooks and smaller local models.Recommended devicesA configurable desktop for experimentation, with an appropriately selected GPU where needed.Nova 520Nova 720
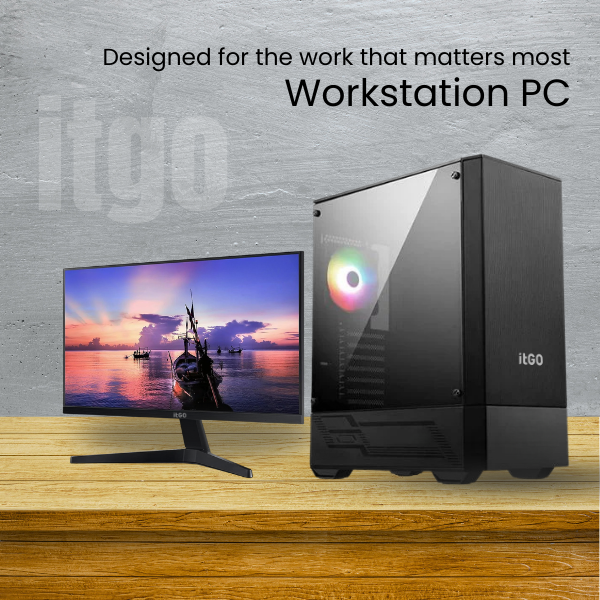
02Generative AI & LLM DevelopmentLocal assistants, RAG pipelines, model evaluation and private inference.Recommended devicesHigh-performance workstations configurable with high-end NVIDIA graphics and large memory.Proxima 910Apex 720Apex 920
03Computer VisionInspection, OCR, video analytics and imaging model development.Recommended devicesGPU workstations for training; compact mini PCs as edge endpoints for validated, lightweight inference.Proxima 710Proxima 910Atom 910Orion 920
04Data Science & AnalyticsLarge datasets, forecasting, feature engineering and accelerated notebooks.Recommended devicesWorkstations with high memory capacity and fast NVMe storage.Apex 920Apex 1020Proxima 1010
05Fine-tuning, Simulation & ResearchSustained training runs, CAE, scientific computing and large memory footprints.Recommended devicesXeon-class and top-tier AMD workstations with expansion for professional GPUs.Proxima 1010Apex 1030
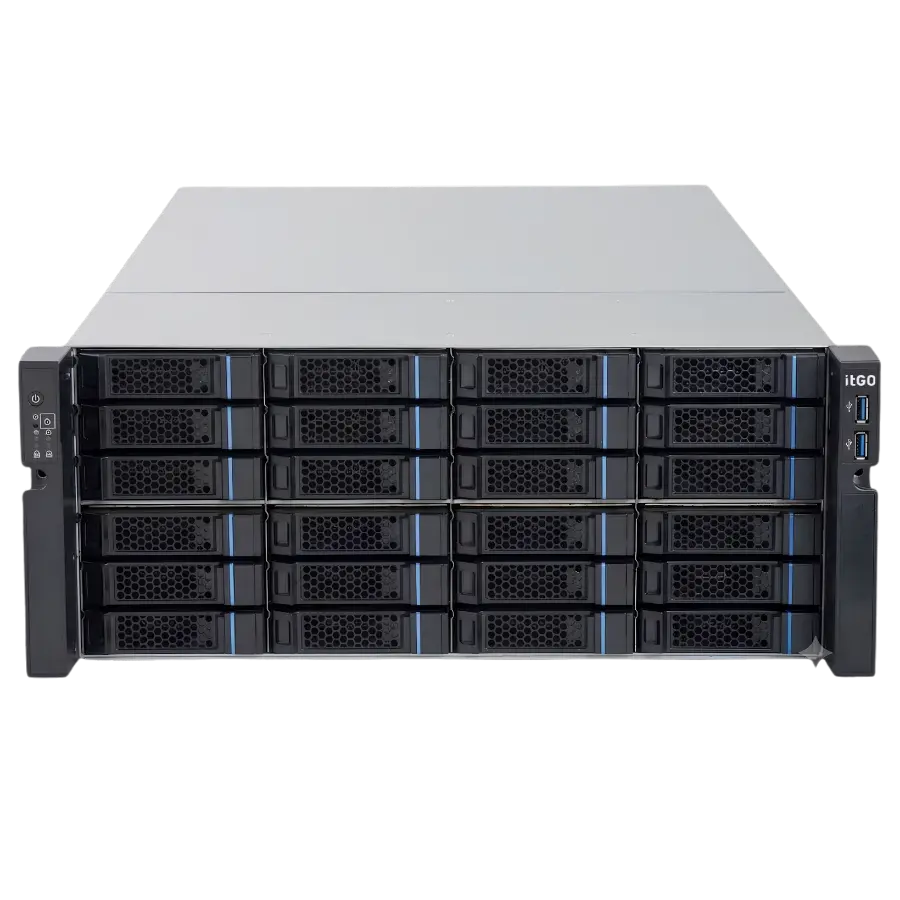
06Shared Inference & Model ServingCentral AI services, multi-user GPU access and production model serving.Recommended devicesCatalyst servers sized from model, concurrency, GPU memory and data pipeline.Catalyst CX-9000Catalyst CX-12000Catalyst AX-6000Catalyst AX-14000
Who we build AI systems for

From one developer to a department-wide AI platform

Start with a validated proof of concept and keep a clear path to shared, rack-scale or production infrastructure.

✓  Startups & Product TeamsDeveloper workstations and a shared inference server for building AI-powered products.
✓  Enterprise AI & Analytics TeamsPrivate GenAI, document intelligence and analytics on controlled, on-premise hardware.
✓  Manufacturing & QualityVision-based inspection with training workstations and edge endpoints on the line.
✓  Media, VFX & 3D StudiosRendering, AI-assisted editing and creative pipelines on GPU workstations.
✓  Research Labs & UniversitiesFaculty research, student projects and departmental GPU servers.
✓  Engineering & SimulationGPU-accelerated CAE, scientific computing and visualisation workloads.
Software & platform readiness

Compatible with leading AI development ecosystems

We configure the platform around the required accelerator vendor, operating system, framework versions, model size and deployment target.

FrameworksPyTorchTensorFlowKerasONNX Runtimescikit-learnXGBoost
GPU & AccelerationNVIDIA CUDAcuDNNTensorRTNVIDIA AI EnterpriseAMD ROCmOpenVINO
GenAI & Data ScienceHugging FaceJupyterLabAnacondaLangChainOllamaMLflowRAPIDS
Deployment & MLOpsDockerKubernetesNVIDIA Container ToolkitKubeflowGitLinuxWindows

Compatibility depends on the selected hardware configuration, operating system, drivers, application version and software-vendor requirements. Third-party licences and vendor certifications are supplied separately where applicable. Device recommendations are indicative starting points; final configuration is confirmed for your requirement.

Delivery methodology

From discovery to dependable operations

One accountable team coordinates solution design, validation, fulfilment, deployment and support so technical and procurement stakeholders have clear ownership at every stage.

01 · ProfileModel, data, precision, latency and concurrency.
02 · ArchitectGPU, CPU, RAM, storage, network and power.
03 · ValidateFramework, driver, container and benchmark testing.
04 · DeployImaging, integration, documentation and handover.
05 · ScaleSupport, monitoring and capacity roadmap.
Talk to a solution specialist

Turn your AI workload into a validated bill of materials.

Share the model, dataset size, framework, user count and performance objective. Our specialists will recommend an architecture without unnecessary oversizing.

WhatsApp